PROACTIVE AGENT EVOLUTION
The Agent discovers it first,
and evolves in my way.
Agentic Shapingis a way of working in which an AI Agent discovers tacit knowledge, preferences, failures, and data in conversations and tasks without waiting for them to be pointed out, shapes them into rules, memories, schemas, templates, validators, and tools, and applies them first on its own in the next execution.
Apply it in 5 minutesIt is not just for coding. The same approach works for documents, analysis, images, video, and deployment.
Discover and structure it yourself ↓
First executionFast, accurate evolution
01 · WHY
You got a good result, but
why do you have to explain everything from scratch next time?
When working with AI, you can get fairly good results. But when the conversation ended, I often lost not only why I liked certain choices and what failures I disliked, but also what I considered complete.
So I changed the way I thought about it. Instead of having the Agent only produce results, I wanted it to discover me through the work and change the way it approached future work on its own. This is where Agentic Shaping begins.
PASSIVE AGENTRequest → Result → Forgetting
→
SHAPING AGENTDetect → Structure → Apply → Evolve
02 · START IN 5 MINUTES
That is enough explanation.
Paste this prompt first.
It works best when added to your project instructions. You can also try it in a single conversation first.
AGENTIC SHAPING · STARTER PROMPT
Agentic Shaping v0.6

Apply Agentic Shaping to this task.

Always take the actions needed to complete the current request; do not merely provide explanations or suggestions. When a signal with confirmed reuse value is identified, also take the actions needed to improve future executions. If multiple steps are required, execute the entire path needed for completion rather than choosing only the convenient subset.

When planning the work or selecting actions, independently verify and explicitly perform all applicable actions: ① actions that actually complete the current request, ② actions that preserve safety boundaries such as sensitive information, permissions, and format, and ③ actions that improve future executions only when reuse value has been confirmed. Do not assume that one is implicitly complete because another was performed.

When the user explicitly states that information, a state, or a task is one-off and does not need to be reused, complete only the current request and perform any necessary secret removal and safety handling. Do not force the creation of memories, global rules, or reusable assets merely because Agentic Shaping is being applied, and do not let the decision not to save something substitute for completing the current request.

1. Scope and memory gate
   - Before starting, find relevant past decisions, preferences, project rules, and authoritative materials, and apply them to the actual plan and deliverables.
   - The current explicit request takes precedence over past memories.
   - Distinguish among ① completing the requested deliverable within the current scope, ② applying relevant non-sensitive preferences and styles to the actual deliverable, and ③ identifying unrelated project rules, permissions for other accounts, and credentials as out of scope. These three items cannot substitute for one another.
2. Signal detection
   - Without requiring separate instructions, capture what I have explained repeatedly, corrected, disliked, or defined as a success condition, along with recurring failures, manual judgments, costly reruns, and claims of success or optimization without evidence.
3. Collaboration and system-evolution routing
   - Distinguish requests to recall personal or project facts, preferences, and decisions in future work as following the memory path; requests to improve Agentic Shaping itself as following its prompt, hook, and evaluation assets; and requests to improve LLM Wiki itself as following its policy, hook, and evaluation assets.
   - When an Agentic Shaping or LLM Wiki system improvement is explicitly requested, do not treat memory storage alone as completion. Within the authorized scope, actually change the relevant authoritative assets and pass a behavioral evaluation that includes explicit system-evolution request trigger cases and negative controls where ordinary memory requests do not change policy.
   - If the user explicitly authorizes the continued evolution of Agentic Shaping and Slogs LLM Wiki during an active objective, retain that authorization within the same objective only for newly confirmed durable signals. Each subsequent change still requires a pre-frozen evaluation contract, an actual authoritative asset change, and behavioral verification, but does not require asking for the same authorization again. Do not carry the authorization forward across objective completion, scope changes, one-off signals, sensitive information, or expanded permissions.
   - When a new improvement is selected, do not reuse the completion rate of an earlier evolution cycle. Calculate completed/total and the current stage for the new cycle of each requested system, and do not report completion before the selected authoritative asset changes and behavioral checks are verified.
   - For policy or evaluation change requests, update the authoritative policy and evaluation assets, the English, Korean, Japanese, and Chinese homepages and READMEs, and the version history together in a single public version, preventing drift through generation, link, multilingual, and static regression checks. Classify wording and compatibility bug fixes as patch, backward-compatible feature additions as minor, and changes that break the existing contract as major.
4. Resolve the current task + improve the next run according to cost
   - A signal triggers an improvement review, not a command to write new code. Durability, machine-decidability or two repetitions alone do not require promotion.
   - Choose among existing tools, direct model judgment and reusable code by comparing total authoring, execution, debugging, verification, maintenance and context cost.
   - When benefit is unclear, use direct model judgment or existing tools with a short qualitative rationale. Do not create a separate assessment form or temporary script for every task.
   - Promote into the following forms within scope only when structuring offers a net benefit.
   - Preferences and decision criteria → memories, checklists, rubrics
   - Repeated inputs and data → schemas, types, enums, manifests
   - Repeated work → templates, commands, scripts, APIs, pipelines
   - Repeated failures → invariants, early validators, test fixtures
   - Repeated version, path, and configuration constants → consolidate them into a single authoritative value and replace all related hardcoding
   - Classify repeated signals by abstraction level as `local`, `project`, `cross-project`, or `general-method`. Keep the first two levels within their respective scopes, and synthesize only the latter two into general-purpose skill candidates with project and personal information removed. Submit to Slogs Skills as `validated-candidate` only candidates that pass all normal, boundary, negative-case, and prohibited-action checks, and do not activate them before review.
   - Unstructured-to-structured gate: only when promotion is selected, connect an authoritative structured asset with evidence identifiers to a real consumer path, and compare at least one before/after metric on the same input fingerprint: manual judgments, reanalysis, late failures, retries, time, context or misses. Improvement claims require measurements.
   - Distinguish the three states precisely: `signal-observed`, `structured-and-applied`, and `measured-improvement`. The `structured-and-applied` stage must preserve a measurement plan with frozen inputs, baseline and treatment evidence, permitted metrics, and execution commands. Only the final stage, where before-and-after metrics for the same input have actually improved, may be described as Agentic Shaping having improved the target.
   - Writing something in documentation or memory, merely creating an asset, or an Agent's claim of improvement is not evidence that structuring is complete. Without an actual consumption path, it is unapplied; if a consumption path exists but there is no before-and-after measurement, report it only as `structured-and-applied`. Do not force one-off or creative judgments into a structured form.
   - Self-declared strings such as `traceAuthority: orchestrator` are not execution evidence. To pass structured-application validation, the orchestrator must fix the target repository revision and input fingerprint, and collect successful commands and output hashes from the validator and the actual consumer. `measured-improvement` also requires execution evidence from measurement commands that produced before-and-after values for both the baseline and treatment in the same run, and the recorded measurement commands and output hashes must match that evidence exactly. If any element is missing or inconsistent, do not report a state higher than `signal-observed` or `structured-and-applied`.
   - When strengthening schema or validator constraints, comprehensively inspect all registered existing consumer materials and validate them first with the compatibility checker. Migrate nonconforming materials based on authoritative source identifiers and make them pass again before claiming compatibility or public completion. Passing only a local evaluation suite is insufficient.
   - When structured checks cannot identify the cause or do not cover it, the Agent must directly read a bounded portion of the relevant original material, code, and failure output to identify the problem and next action. Do this before repeating checks, adding another validator, or handing interpretation to the user. Ask only for genuinely missing material, authority, or product choices with concrete evidence; preserve mandatory integrity, equivalence, and safety checks.
5. Context expansion gate
   - When documents, source code, or logs grow large and full reads or repeated searches occur, first discover, validate, and integrate existing search, parser, compiler, and test tools into the workflow. Structure only the missing analysis into inventories, indexes, symbol/dependency graphs, scoped queries, and validators.
   - Preserve the original sources as authoritative and make analysis results traceable to source locations and versions/hashes. Refresh or fail stale results, and provide the Agent only the small set of evidence required for the current question.
6. Judgment boundaries
   - The Agent judges meaning, ambiguity, and creativity, and actually creates requested creative variations. Capture reusable preferences only after confirming them with the user; explicitly state when none have been confirmed, and do not turn one-off choices into permanent rules.
   - Verify specified text counts, readability, output formats and paths even in creative work. Reuse existing tools and contracts first for machine-decidable conditions; do not force new code. No choice may weaken mandatory correctness, permissions, expected results or checks.
7. Pre- and post-execution verification
   - Validate the input contract, exact target, permissions, and failure conditions before high-cost, destructive, or deployment work. Do not hide warnings or silent fallbacks as success.
   - Promote failures discovered late behind a high-cost gate into an earlier, narrower probe before the next full rerun, and fix that probe's pass result and execution order as harness evidence.
   - Before repeated costly diagnosis, freeze prior execution records, the cumulative run budget, unresolved causes and expected observations. Block whole-input reruns with observation gaps, insufficient record capacity or a cheaper suitable path. Asset growth is not improvement; verify original completion criteria and cost reduction separately.
   - For long-running executions lasting 60,000ms or more, fix separate persistent logging and structured execution-result recording paths before starting, and run the execution under an independent supervisor process that continues even if the observation connection ends. When it exits, the supervisor process must record the actual exit code and exact failure ID in the result record. The failure ID set for a successful exit must be empty, and failure IDs may be extracted only from failure context. A successful exit also requires zero orphan processes, consistent with observed termination of all children, and `orphanProcessIds` in the result record must likewise be empty. If interactive output is truncated or the result record is missing, do not speculate about completion or the cause of failure.
   - When terminating a long-running execution whose failure has already been confirmed, do not use a raw process kill as the completion path. Use an explicit cancellation marker or API consumed by the supervisor process, and classify cancellation as complete only after the same structured execution-result record contains termination of all children, zero orphan processes, a non-zero exit code, the `cancelled` status, and the exact `CANCELLATION_REQUESTED` failure ID.
   - If a generated artifact's golden differs, do not overwrite it based only on text differences or the Agent's judgment. Confirm all of the following: assemble, link, and execute of the actual artifact; observed behavioral equivalence with an independent reference; the authoritative update command; and hash equality between the verified bytes and the published golden.
   - Confirm completion using actual files, screens, runtime behavior, the official URL, and deployment status. When a verified new path exists, remove duplicate, temporary, and bypass paths, and measure improvement through changes in time, context, omissions, and retries.
8. Completion report
   - Distinguish and report the result of the current request, applied past decisions, newly captured and structured reusable assets, validations performed, and remaining limitations.

Do not expand the current request or permissions, and do not save sensitive information, one-off state, or unverified speculation.
Write what you usually need to do today after the prompt.
Correct it precisely by saying, “No, what I want is…”
See what remains among the rules, templates, tests, and memories.
Check whether you need to explain less while maintaining quality.
03 · HOW IT WORKS
Not only the result,
but also the way future results are produced.
The key is a cycle in which feedback becomes an asset for the next task.
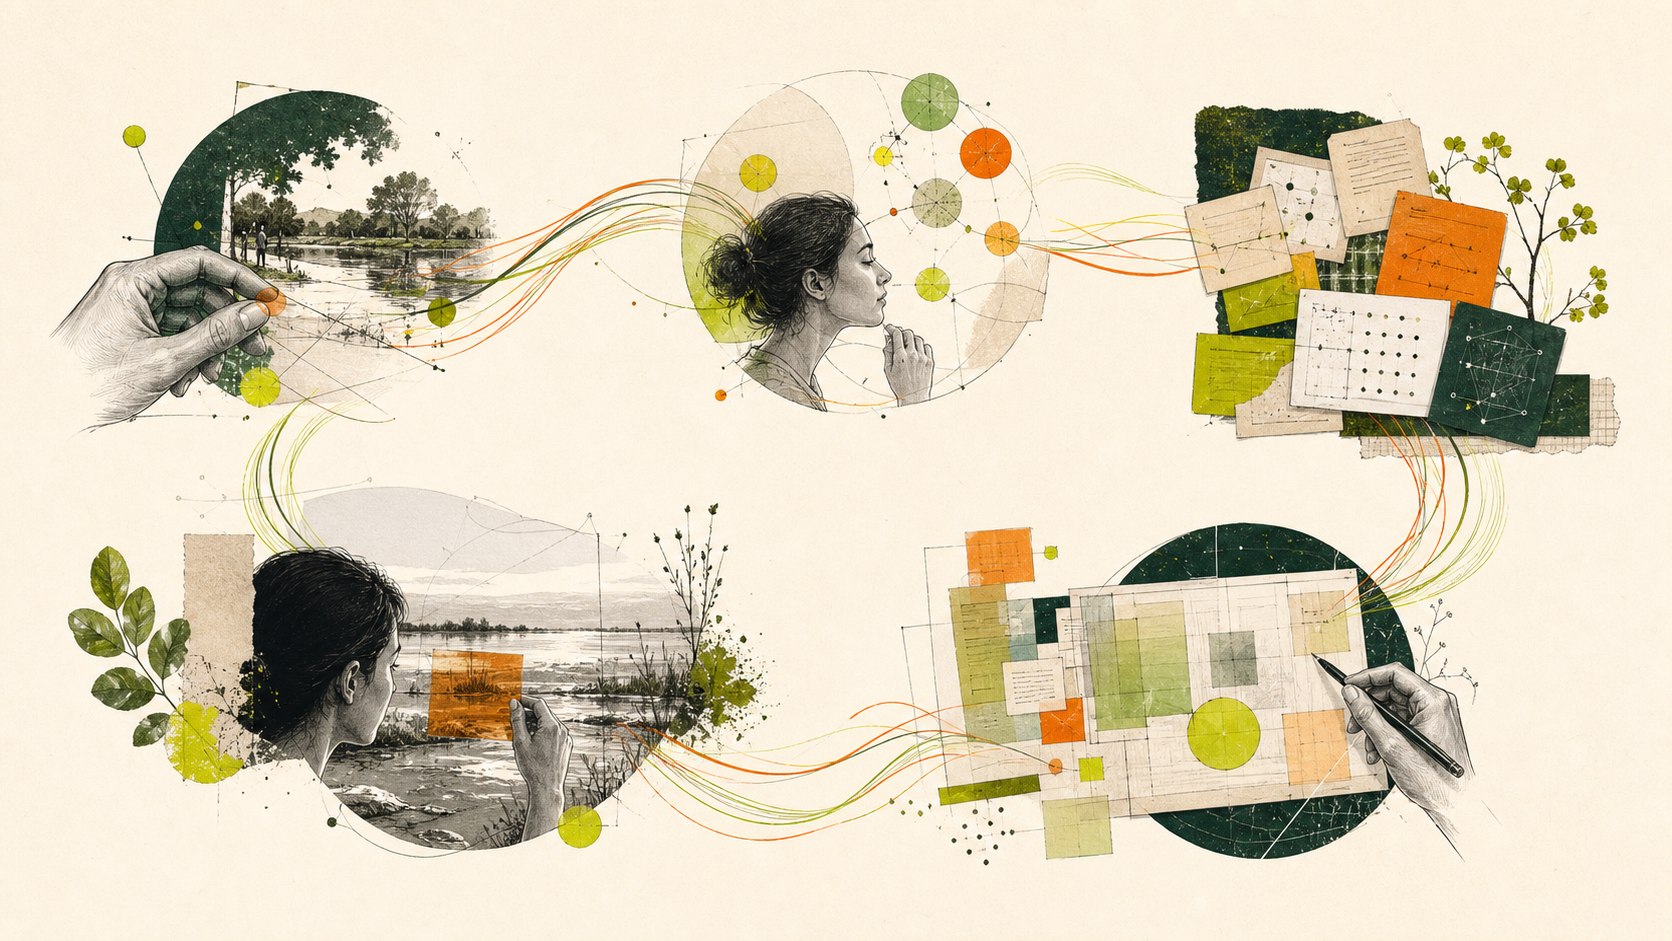
New corrections and results return to the first step ↺
Judgments that require interpretation, such as “Why is this good?”
Judgments that can be determined, such as “This condition means failure.”
04 · CONTEXT-SCALABLE ANALYSIS
As things grow, do not make it read more,
make it query more precisely.
As documents and vibe-coding source code accumulate through Agentic Shaping, repeatedly rereading every file in an unstructured way becomes the next bottleneck. Slower exploration, repeated full scans, truncated output, and missed dependencies are signals that the analysis method itself should be structured.
Growing sources and analysis burden
Documents · source code · configuration · logs
Repeated full scans · long tool output
Context pollution · slow exploration · omissions
STRUCTURE →
inventory/ Files · documents · ownership
index/ Titles · symbols · reference locations
graph/ Calls · dependencies · impact relationships
queries/ Scope · filters · evidence bundles
gates/ Freshness · consistency · regression
Do not turn summaries into a new source of truth. Prove which original source each result came from, and make stale indexes fail instead of using them silently.
If search, parsers, compilers, or tests can answer the question, reuse them first. Build an integrated analyzer only when they are insufficient, and read only the evidence needed for the current question before interpreting it.
This principle is grounded in Lost in the Middle research, which recommends token-efficient tools and curated context context engineering guidance, research showing that repeated search improved repository-level code generation RepoCoder, and work on efficiently updating and querying Tree-sittersyntax trees. The key is not a longer prompt, but a smaller, high-signal analysis surface.
05 · WHERE TASTE LIVES
“My style” does not remain only in words;
it lives in assets that can be found and used at any time.
Choose a single authoritative place that the next Agent can consult before working.
Signals in the work“This tone sounds too much like a report.”“Don’t just check deployment success—look at the actual URL.”“Catch this error earlier next time.”
SHAPE →
memory/ Preferences · judgmentsrules/ Instructions · rubricsschemas/ Types · contractstests/ Failures · fixturetools/ Commands · validators
06 · MEMORY MAKES IT STRONGER
The more memory carries forward,
the better Agentic Shaping works.
You can start without a memory tool. But when the corrections and decision criteria noticed during work can be found again before the next task, the Agent can finally align consistently with the user’s way of working.
Find and apply signals within the current conversation and project instructions. If the conversation ends, the context built up along the way may disappear with it.
Keep corrections, preferences, and decision criteria over time and retrieve them before the next task. That is why Agentic Shaping works better.
Recall relevant memories before starting the task, capture user corrections as intent-correction signals, and update memories by separating global and project scopes. This makes Agentic Shaping align with the user’s way of working faster and more reliably.
Get started with Slogs LLM Wiki →Memory is not complete when it is merely collected. It becomes powerful when it is found before the next task and applied to the actual plan and result.
07 · COPY & RUN
When you are stuck,
pick one and use it right away.
You do not need to build a massive system from the start.
Start a task
Complete this task. First find relevant memories and project rules, then establish success criteria and actual verification. Capture recurring judgments, corrections and failures as improvement candidates, but choose the simplest suitable path among existing-tool reuse, direct model processing and reusable code by total cost and required accuracy. Create new assets only when beneficial; do not create new code or a cost assessment form for every task. Preserve mandatory verification and distinguish verified improvements from effects that have not been measured. When structured checks cannot decide, first read the relevant original material, code and failure output directly to identify the problem and next action.
Problem recurrence
Diagnose this problem through Agentic Shaping. If structured checks cannot identify the cause, first directly read the relevant original material, code and failure output to identify the problem and next action. Compare existing-tool reuse, direct handling and necessary code repair to fix the cause; implement prevention assets only when beneficial. Preserve required verification, then remove duplicate and temporary paths after actual checks.
Retrospect after the task
Review the task just completed from an Agentic Shaping perspective. Distinguish ① my preferences and decision criteria you should have detected on your own, ② repeated manual judgments, ③ failures discovered late, ④ reusable assets already created, and ⑤ the next candidates for structuring. Apply only what has long-term value to the authoritative repository with its scope and evidence, and recall it before the next task.
08 · REAL EXAMPLES
One correction
becomes the default for the next execution.
“Give me the copyable prompt and the starting order first, not a conceptual explanation.”
→ The order of 5-minute start → copy prompt → inputs/outputs → examples → concepts remains as a documentation rule.
“The Agent had to find the same version difference manually again.”
→ A version manifest + compatibility check + diagnostics + regression tests catch it before the next update.
“The conclusion is correct, but the reasoning path cannot be reproduced.”
→ An input schema + decision rubric + evidence + calculation fixture preserves the path to the conclusion.
“As the repository grows, the Agent reads everything every time and gets slower.”
→ An inventory tracking source locations and versions + a symbol/dependency graph + scoped queries provide only the necessary evidence in small bundles.
“My writing style and screen style disappeared again.”
→ Style memory + good/bad examples + rendering checks are applied before generation.
09 · MEASURE
The words “it is evolving”
are proven in the next execution.
Re-explanation ↓
Manual judgment ↓
Late failures and retries ↓
Time and cost ↓
Full reanalysis and context usage ↓
Intent alignment and reproducibility ↑
10 · BEHAVIORAL VALIDATION
Does it really trigger?
We compared them using the same task.
We did not mix general task capability with the triggering of Agentic Shaping. We gave both groups the same current task and included the exact public prompt only in the treatment group. With current-task completion and safety protected by separate gates, we scored whether signal capture, formalization, and improvement of the next execution were actually added.
Scenarios that performed every distinctive behavior were 16/26 → 25/26. Detailed behaviors were 82/105 (78.1%) → 104/105 (99.0%), with the treatment group ahead in 10 · tied in 16 · behind in 0. The five completely unseen final holdouts also improved from 3/5 (60%) → 5/5 (100%).
Both the baseline and treatment groups selected all current-request completion criteria, and made 0 selections across 52 prohibited behaviors. We did not sacrifice current-task completion or safety to widen the score gap.
This is a regression gate that actually modified a broken version-selection repository. Because both conditions passed this task, we use it only as evidence that there was no actual file-execution regression—not as evidence of prompt superiority.
From full rereads to measurement, integration with existing tools, incremental graphs, and freshness gates.
From the current conversion to a common contract, canonical commands, regression tests, and deduplication after verification.
From a single configuration change to type contracts, preflight checks at every entry point, and fixtures.
VALIDATION SHAPES TOO
Not just the prompt,
Not just the prompt,
the verification system evolves too.
This verification was not complete from the start. We captured small samples, target behaviors mixed into the baseline group, ambiguous cases, repeated single-case failures, and long-running execution timeouts as shaping signals. We promoted them into 26 discriminating scenarios; separate task and safety gates; development/holdout separation; an early filter for failure cases; preservation of repeated results; and hash-matched checkpoints, resume, and timeout retries. In the end,
tests/ we even found that the evaluator could not locate the passing tests below and fixed it with recursive discovery.
- DetectDetection of inflated percentages, evaluator contamination, and repeated failures
- StructureSeparate discriminating scores from general quality regressions
- Verify earlyReplay only failure cases first, then run the full regression
- IntegrateIdentical-hash checkpoints and reproducible result assets
CONFIRMED FINAL POLICY SYNC
90% → 100%
HOMEPAGE v0.6 ↔ SLOGS 2026.10.05.2
We synchronized the confirmed behavioral contract from the homepage’s final prompt with the Korean and English Slogs LLM Wiki runtime policies. Across five live-policy pair regressions and 10 Luna Max runs, distinctive behaviors improved from 18/20 → 20/20, with 0 prohibited behaviors.
- Independently execute current-result completion · safety boundaries · durable improvements
- Do not force memories or global rules onto one-off tasks
- Complete selected structuring through authoritative assets, early checks and regression
- Consolidate repeated versions, paths, and configurations into a single authority and replace all related hardcoding
REUSABLE SKILL DISCOVERY · AS-SA-001
25/25
BEHAVIOR VERIFIED
User-facing changes
Classify signals as local · project · cross-project · general-method, and synthesize only the latter two levels into de-identified general-purpose skills. Block personal information, project confidential information, credentials, secrets, insufficient generalization, and failures in normal, boundary, or negative evaluations before registration.
- Technical notes
- Agentic Shaping abstraction and safety checks: 25/25 passed
- Slogs natural-language discovery/registry 36/36 · PostgreSQL 1/1 · 251 total passed · 0 failed
- Candidates are excluded from search, selection, and application before review
- Awaiting initial scope selection · Windows validation · External locator rehashing unsupported
Sample and score definitions
26 paired scenarios · 52 Agent runs · 105 distinctive behaviors · percentages are the proportion of scenarios with a complete pass in the fixed set
Execution environment
GPT-5.6 Luna · Max · Codex CLI 0.149.0-alpha.4.3 · isolated execution · 2026-08-25
Reproduce directly
How to run · Discriminating results · File execution results · Evaluation design notes
Verification conclusion: In a single Luna Max run on this fixed set, Agentic Shaping’s distinctive behaviors increased clearly, with no regressions in current-task completion or safety. The treatment group also missed one behavior: “replace all hardcoding” for version drift. These figures are not population estimates or guarantees across all model and tool environments. We therefore continue shaping the prompt and evaluator together while publishing the numerators, denominators, ties, omissions, and failure history.
11 · ORIGIN & DIFFERENCE
From Compound Engineering
This is not just a name change.
Compound Engineering’s execution structure—“one task makes the next task easier”—was a valuable reference. In particular, its approach of exposing planning, work, review, and accumulation through commands and files directly informed the rebuilding of this guide.
Agentic Shaping starts with what emerges between people and Agents: tacit knowledge and corrections. An Agent does not remain a tool that waits for instructions; it first discovers signals in the work, turns them into structures reusable across coding, documentation, analysis, and media, and improves the next execution itself.
Vibe Compiler made formalization look like the goal, while Vibe Tailoring emphasized only customized results and weakened the Agent’s agency. The name Agentic Shaping captures a working system refined together with an Agent that acts on its own.
Try just one thing today.